Experiments and notes on AI.

I'm Wes Herzik. Here, I share what I'm working on, experimenting with, and curious about.

I have worked on digital products and platforms for nineteen years, including eight years leading AI projects at Dell and JPMorgan Chase. AI comes up often because I enjoy it, and it shapes how I build. But what holds my attention is making things simpler for the people who use them. I like taking a process that has grown complicated and finding the version that feels easy, where each step earns its place, and the rest falls away. That usually means understanding the larger system a process sits inside, the handoffs, incentives, and quiet dependencies that shape how it behaves long before anyone notices.

Right now I am most interested in how agents, robots, and automated systems work together in warehouses, supply chains, and other large networks, especially as more of the computing moves to the edge and the physical and digital sides of a business start to run as one. Lately, that has me building digital twins from real operating data, which lets me prototype an idea and quickly see whether it holds up. I am also studying for an MBA at UT Austin to sharpen how I tie the systems I build to financial outcomes, meet people from other fields, and challenge some of my own views.

Things I've built

Two multi-agent systems I designed, built, and run. Both are live. Try them, or write me for the working notes behind how they were made.

Multi-agent system·Five agents·Live

Agent Advisory

Helps a business decide whether an autonomous agent should launch before it starts acting on customers or operations.

Organizations are moving autonomous agents into customer and employee operations faster than they can decide whether those agents should launch, what rules apply, and what a reviewer can actually verify. That gap is a business risk, not a paperwork problem.

Agent Advisory looks at a proposed or deployed agent and comes back with a governance verdict of launch, launch with conditions, or do not launch. Every verdict is tied to the regulatory clauses behind it, and if the system cannot cite a source it says there is not enough information rather than making something up. Five specialized agents do that work together, and the result is signed so a reviewer can check it later.

Multi-agent system·Four agents·Live

Agentic Discovery Engine

Helps a team turn an early opportunity into an evidence-backed direction before the build gets locked in.

The costly mistakes in product and strategy happen early, when a team has an ambiguous opportunity and not enough evidence to choose a direction. Discovery gets skipped or done unevenly, and the roadmap hardens anyway.

Four reasoning agents take a question that is still forming and return a working hypothesis, the evidence behind it, the constraints and risks, and an honest read on confidence. You get a structured starting point you can challenge or build on, while you stay in the lead and can see where the ground is firm.

Writing

How the work actually lands inside an enterprise. Four pieces so far. Start with whichever is closest to what you're facing.

From work at a large bank

Working through complex account opening.

At a large bank, opening a complex account could take one to three weeks. We examined the process to reduce the time involved and identify capabilities that could support modernization across other account types and parts of the business.

Customers often started without the right documents or clear instructions on what to provide. They might upload a document but not know if it was received. Bankers sometimes could not see what specialists had already checked, so the next person had to figure out what happened before moving forward. Sometimes, people only realized a case was stuck when there was no further communication.

Understanding the work together

We explored those problems through more than thirty interviews and a two-day session with about fifty participants, including customers, bankers, front-office and back-office specialists, and product teams. Working through the process together gave people a chance to explain what they encountered and hear what happened elsewhere in the new-and-existing account opening process.

A question that seemed simple to a customer could leave a banker looking for help or a specialist trying to figure out which documents were already checked. As participants followed these situations, they found steps customers could do on their own, tasks that could be automated, and ways AI could help with documents, guidance, and routing.

These activities gave us a basic view of the problems and possible solutions. They also showed that better technology alone would not fix everything. The bank's current policies and incentives encouraged assisted service, even when customers could do the work themselves. To expand self-service, the bank would need to change how it supports and promotes it.

The trust-account scenario gave everyone a clear example to work with. It combined documents, specialist judgment, customer support, and handoffs, which helped us see needs that showed up in other cases too. This let us think about where one solution could fix the same problem in different parts of the business.

From discovery to shared capabilities

We turned what we learned into a service blueprint that linked the customer journey to the work of bankers and specialists, the information they needed, and the systems they used. We also created prototypes as part of the next steps. Since these materials have confidential details, the blueprint shown here is blurred.

Service blueprint for complex account opening, blurred for confidentiality. Lanes run from the customer journey through banker and specialist work to shared capabilities and systems.

Tracking a missing document through the process shows how the blueprint helped. Before applying, the customer needed to know which documents to prepare. After sending them in, they needed to find out if anything was missing or needed attention. A specialist had to see what was received and reviewed. If the customer visited a branch, the banker needed to know why they came and what they were supposed to bring.

Looking at these dependencies helped us spot key needs that came up often, like document processing, shared records, notifications, routing, and access to guidance. A conversation summary could help a specialist take over from an AI assistant and help another employee understand the work later.

The blueprint also grouped and organized capabilities, giving the work more structure than just a list of ideas. These groupings supported the larger modernization effort, and some of the capabilities were later used in other parts of the business.

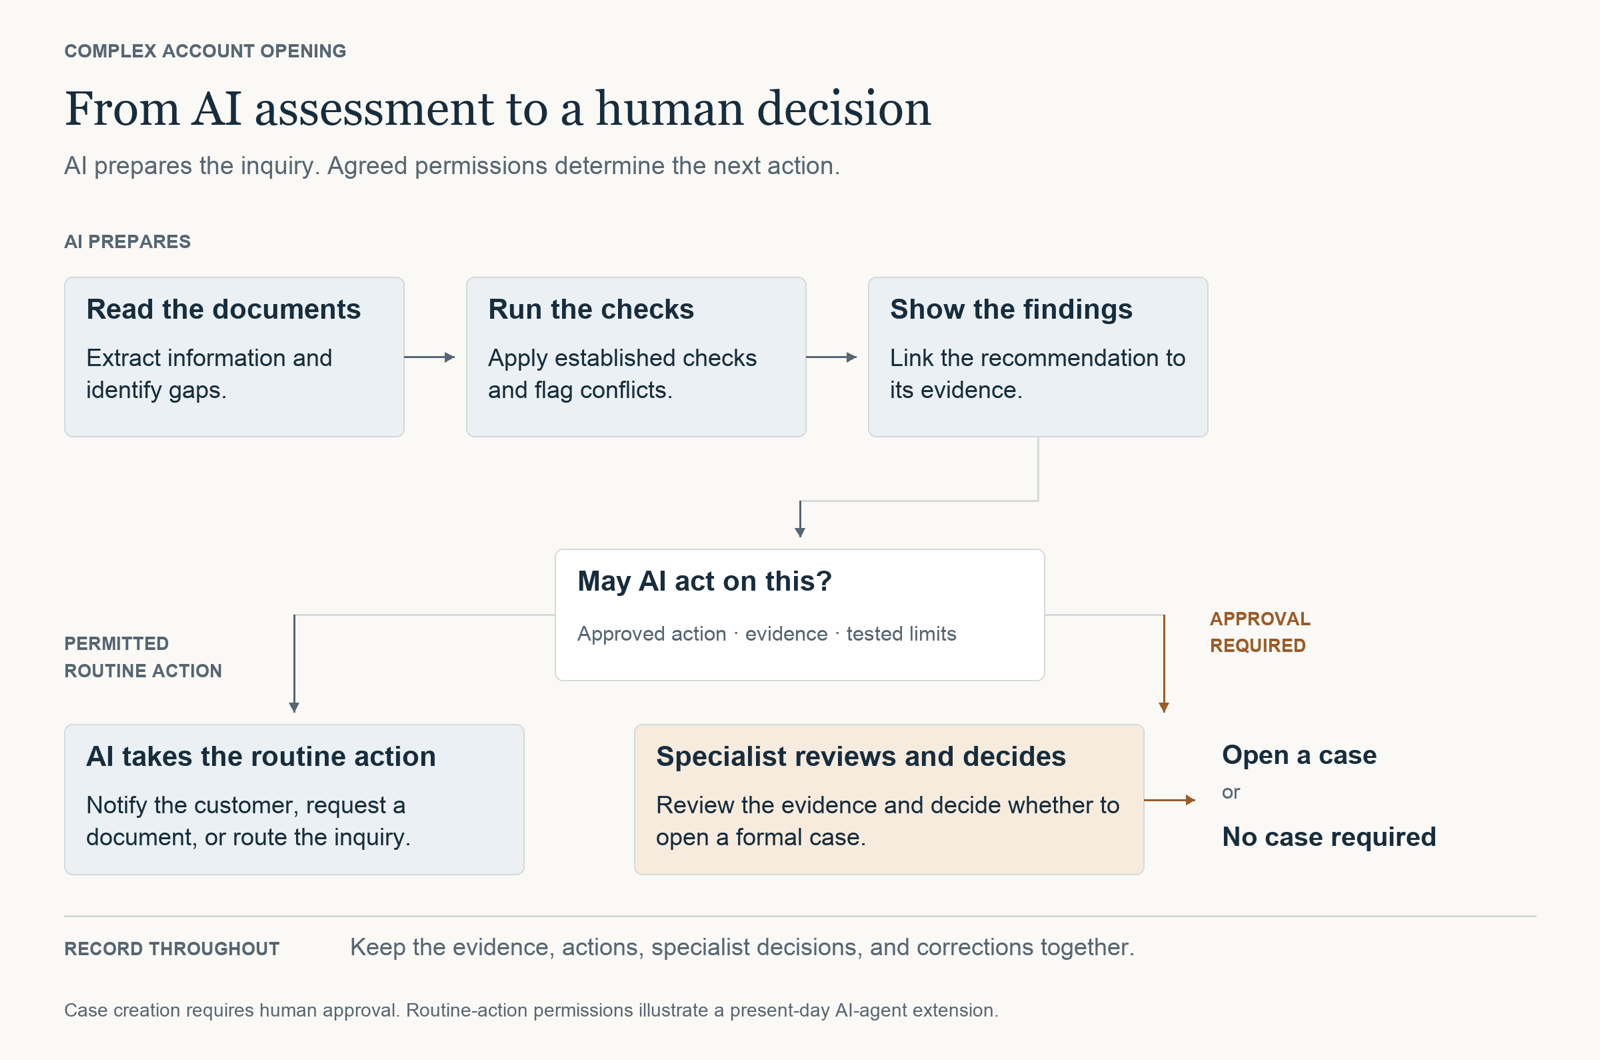
In this work, we separated regular workflow improvements from AI opportunities. Upload confirmations and shared status could fix some delays without using AI. AI could read documents, prepare information for review, and help decide where the work should go next.

Diagram: From AI assessment to a human decision. AI reads the documents, runs the checks and shows the findings. If the action is permitted, AI takes the routine action; if approval is required, a specialist reviews and decides whether to open a case. The evidence, actions, decisions and corrections are recorded throughout.

Participants saw document processing and routing as the capabilities with the most potential impact. Document processing still needed more study and testing. Extracting information accurately, checking if everything was complete, and confirming authenticity each had different needs and needed to be evaluated for the work they would support.

Connecting the improvements to the outcome

Cutting the time to open an account depended on how well these changes worked together. Faster document review could help, but customers would still wait if their application sat in a queue or reached someone without the right information. Policies and incentives that favored assisted service also mattered, since they could keep customers relying on employees for steps they could do themselves.

We measured progress across the full process, tracking the time from the first request to the account decision, repeated document requests, handoffs, and employee time per application. This helped us see whether faster work at one step reduced the overall turnaround or simply moved the application into another queue.

For capabilities that went live elsewhere in the business, we followed those measures after deployment to understand how time savings translated into operating results. We examined whether teams could handle more work, devote more attention to exceptions, or help more customers complete the process. We distinguished those results from estimated hours saved when assessing the financial benefit.

Following the AI opportunity through the process

Work on new and existing customer account opening helped us identify needs shared across critical functions of the business. We translated the findings into capabilities and delivery bundles, some of which went live elsewhere in the organization. We then tracked whether process improvements translated into greater capacity, more completed applications, and measurable financial benefit.

That experience informs how I approach AI today. Understanding the hidden gaps in systems and experiences helps establish where AI can contribute, what employees remain responsible for, and which policies and incentives need to change.

Following the work on complex account opening

When several AI agents work on a new account application.

A customer uploads a missing document but is asked to resubmit it shortly after. One part of the system records the upload, while another relies on outdated information. By the time a specialist intervenes, the customer has already called to confirm receipt.

As previously noted in account opening, similar gaps exist between employees, teams, and systems. If multiple AI agents are used, we must address how they share information, coordinate actions, and determine when human intervention is required.

Below is how I would extend this approach, using a new account application as an example.

Give each AI agent a defined responsibility

Document review, identifying applicable requirements, and coordinating next steps are distinct tasks. Assigning separate AI agents to each may improve reliability and make the process easier to evaluate.

A document agent could extract information from submitted files, identify gaps or inconsistencies, and link each finding to its source. A requirements agent could retrieve relevant guidance for the account type. A coordinating agent could compare these findings with the current account-opening record and determine the next action.

Each agent would require a defined output. The document agent would report its findings, their sources, and any unresolved items. The requirements agent would specify the guidance used and note any uncertainties. The coordinator would differentiate between missing documents and those received but pending review.

I would compare this division of responsibilities to a simpler approach before implementation. Some steps may be managed by standard software, and a single AI agent with appropriate tools might suffice. Since separate agents increase coordination and operating costs, evaluation should demonstrate clear improvements.

Keep the evidence connected to the work

A new account application consolidates customer documents, bank requirements, and a record of actions taken. An AI agent must interpret each source and assess the information's accuracy.

When a customer uploads a document, the system should update its status to received and initiate the next check. If the customer informs an AI assistant of the upload, the assistant should verify the record and confirm receipt. However, a received file may be unreadable, incomplete, or unsuitable, so its arrival alone does not resolve the issue.

This distinction would guide each agent's next steps. The coordinator should no longer treat the document as missing, while the document agent reviews it. Any further requests should specify the remaining issue, rather than ask the customer to repeat completed steps.

Retrieval-augmented generation (RAG) could help AI agents use relevant information from submitted documents and bank guidance when preparing an assessment or response. Before taking action, the agents would also check the current account-opening record to confirm which files had arrived, which checks were complete, and what had already been requested from the customer.

For example, if a document lists a name differently from the account application, the document agent would flag the discrepancy and retain the relevant passages. The requirements agent could retrieve applicable guidance but may not determine if the difference is acceptable. The coordinator would escalate the unresolved issue to a specialist.

The handoff should retain details of the disagreement. If the coordinator summarizes it as "documents checked," the specialist may miss critical information requiring attention.

Before sending a document request, the workflow should check for recent uploads or outstanding requests. After sending, the system should record the action and its outcome. These checks help prevent duplicate requests or actions based on outdated information.

Make human review part of the running process

The original blueprint, described in Working through complex account opening, assigned the decision to convert a logged inquiry into a formal case to a specialist. I would keep that responsibility with the specialist in a multi-agent implementation.

The specialist would receive the supporting documents, applicable requirements, findings, and unresolved questions together. They could approve the next step, correct a finding, or return the work for clarification. Agreement among AI agents would not replace this review, especially when they relied on the same evidence.

Approval would apply only to the information actually reviewed. If a new document changed a material finding, the affected work would return to the specialist rather than proceed under earlier approval. Other tasks could continue within their agreed permissions. A designated operations owner would monitor recurring errors, unnecessary referrals, and specialist corrections, with authority to restrict automated actions when problems arise.

The measures we established would also carry forward. We tracked turnaround time, repeat document requests, handoffs, and employee effort, then examined how improvements affected capacity, completed applications, and financial benefit. A multi-agent implementation would add coordination and review costs to that assessment.

I would track duplicate requests, failed handoffs, repeated attempts, and the time specialists spend checking or correcting AI findings. These measures would show whether the AI agents reduced work across the process or added enough review to offset time saved elsewhere.

The financial assessment would include both the cost of running the AI agents and the employee time needed to supervise their work and resolve errors. Cost per completed new account application, considered with completion rates and review quality, would help determine whether the changes improved the economics of account opening.
From operating-model work inside a large financial institution

The hidden middle.

Why enterprise AI keeps stalling at the agent layer.

Some organizations have an AI strategy. Many have a wall of pilots. Almost nobody has mapped the layer that should sit underneath both. The operational capabilities AI is actually supposed to act on. Workflows, decisions, escalations, knowledge handoffs, the connective tissue of how work moves. That layer isn't missing. Most of the time, it's hidden.

The pattern I want to describe shows up almost everywhere I've seen enterprise AI attempted, across multiple companies and industries.

In a large enough organization, different teams routinely solve the same problem without realizing it. A workflow team on one product rebuilds the same escalation pattern that another team on another product just shipped under a different name. Multiply that across every product and servicing group in a large enterprise, and you stop seeing dozens of unrelated issues. You start seeing one issue: nobody can see the whole picture, so everyone keeps reinventing the parts.

In one engagement, I ran this exercise directly. A cross-functional group mapped the work at the capability level rather than the workflow level, resulting in 30 macro capabilities, 26 of which were shared across the products in scope. The shared capabilities clustered into three rough layers: data and intelligence, user interaction, and process orchestration and governance. The structure isn't novel. What mattered was having an evidence-backed frame that leaders could plan against.

The inventory wasn't the point. The point was the shift in how teams plan once the middle is no longer hidden. You can have a real conversation about what gets designed once and reused, what gets governed centrally, and what gets owned where. Without that visibility, every team's build brings its own version of the same patterns, governance, controls, and escalation paths. You end up with the same sprawl, just more confident about it.

This matters more than it used to. Hidden middles were tolerable when humans were doing all the work, because humans are flexible. A person can absorb six variants of the same escalation pattern across six products and just figure it out. AI agents and automation can sometimes muddle through, but not reliably, not auditably, and not at scale. They need named, stable, shared capabilities to operate against. An agent that's supposed to handle escalation can't do that dependably if escalation lives as six undocumented variants under six different names. The hidden middle becomes the ceiling on how far AI can scale inside an enterprise. The models can be excellent. If the capabilities underneath them aren't visible, there is no coherent path for the agents to land.

This is the operating-model layer of AI strategy. It is the part most AI programs skip. Strategy teams don't think it's their job. Engineering teams don't think it's their job. The middle stays hidden, builds multiply, three years pass, and someone eventually asks why the AI investment isn't compounding. This is why.

From product strategy on a cloud services platform

Customer feedback in the loop.

Customer feedback must reach the team before the team makes final decisions.

Most organizations agree that understanding customers matters. That part is not in question, and it is rarely where things go wrong.

The greater challenge is ensuring customer evidence informs the decisions that matter. Those decisions determine funding, priorities, risk acceptance, metrics, and which assumptions get to persist. Many teams do strong research, yet their findings still don't reach those decisions.

Part of the reason is historical. For a long time, research lived in its own lane. Researchers did research, product wrote requirements, engineering built, and the work moved between them in handoffs. Research was a phase, usually near the front, with a readout at the end. Once the readout was delivered, the team moved on, and the plan started to harden. That model made it easy for evidence to exist and still arrive too late.

In enterprise settings, this plays out the same way again and again. Teams learn something true about customers after the roadmap has already shifted, engineering tradeoffs are set, and leadership is committed to the existing plan. At that point, the evidence becomes background rather than input.

The issue is rarely a lack of insight. It is a timing problem, and timing problems don't get solved by doing more research in the same old slot.

I worked on a cloud services platform where we ran it differently. The platform was a management console that let customers see what they owned, what they were using, and where they needed to act. The next phase was meant to make it smarter, with prediction, contextual suggestions, better alerts, and automation across the operations that supported customers.

The team didn't need a general summary of customer needs at the start. It needed evidence arriving continuously, close enough to the work to change product direction while that direction was still forming. So instead of running research as a phase, we ran it as part of the build loop. We talked with customers, employees, and the internal experts shaping the experience, but we did it in short cycles tied to specific questions about key moments in the customer lifecycle. Each cycle produced something small to test; the test produced new evidence; and that evidence fed directly back into discussions about roadmap, scope, and direction while those discussions were still open.

That rhythm changed what the team could see. Reporting was fragmented across products customers expected to manage as a single environment. Cost visibility was weak exactly when customers needed to justify spending inside their own companies. Usage monitoring didn't answer the capacity questions customers were actually asking. Trust was eroding during adoption and renewal, when credibility mattered most.

One customer walked us through how she managed her cloud spend and said:

"This is the part where I just open a spreadsheet and do it myself, because the platform doesn't really help here."

That statement stuck because it wasn't a complaint. It was her actual workflow. She was showing us where the platform stopped being useful and where she had built her own operating layer outside it. The issue wasn't a missing feature. It was a decision the product hadn't earned the right to support.

Because this evidence arrived while decisions were still open, the team was able to adjust its approach. Predictive right-sizing addressed the capacity decisions customers faced. Smarter notifications targeted moments when trust was fragile. Reporting was redesigned to align with how customers viewed their environment, rather than the company's internal product structure. These changes resulted from timely evidence, not from a larger research effort.

The key takeaway is the structural choice of where and when evidence enters the work, not the interview count, sprint structure, or research plan.

Customer evidence is only valuable when it reaches decision-makers while changes are still possible. Once funding, scope, staffing, and timelines are locked, evidence has to overcome real momentum to have any effect, and momentum usually wins.

This is why "getting closer to the customer" isn't a specific enough goal. The real question is which decision, at what moment, and with what force to actually change the work. Evidence that arrives after the plan is set becomes context. Evidence that arrives while the plan is still being shaped can change the product, the sequencing, the risk model, and the success metrics.

This matters more now than ever. AI-native teams don't build in a line from research to requirements to engineering. They build in loops. A working prototype can exist in days, sometimes hours, which means the question is no longer whether you understood customers before you built. It's whether what you learn from each experiment makes it back into the next decision fast enough to matter. Research as a separate function, with its own phase and its own readout, can't keep up with that cadence. Evidence has to live inside the loop, owned by the same people making the calls.

This was the key lesson from the cloud platform project, and it is even more relevant today. The team did not need more customer empathy; it needed customer evidence present in the room, in the cycle, at the moment decisions were made.

The solution is not more research or another discovery phase. It is a build rhythm where experimentation, learning, and decision-making occur in the same loop, and customer evidence informs that loop before decisions become too costly to change.

Contact

If something here resonates, whether it is one of the systems or one of the articles, I'd like to hear what you're working on.

Send a note

A short message is fine. Add your email only if you'd like a reply.

Or reach me on LinkedIn

The surest channel. Connect there if you'd rather skip the form, or if the conversation should run in the open.

linkedin.com/in/wesherzik